Prefix caching for prompts: what it is and when it works
When developing advanced LLM applications, the operational costs and processing time of extensive system prompts pose a constant challenge. Every time a user initiates an API call, the application sends along the full instruction set, background documentation, and safety guidelines. This results in repeated computations on the inference server for identical blocks of text. Prefix caching offers an effective solution by storing the computed key and value matrices of the opening text in the working memory of the underlying hardware. In this article, we analyze the technical foundations of this technique, examine how the KV cache works in modern transformer architectures, and discuss how prompt developers structure their code and templates to achieve maximum cost savings and performance gains in real production environments.
1. What is prefix caching at the architectural level?
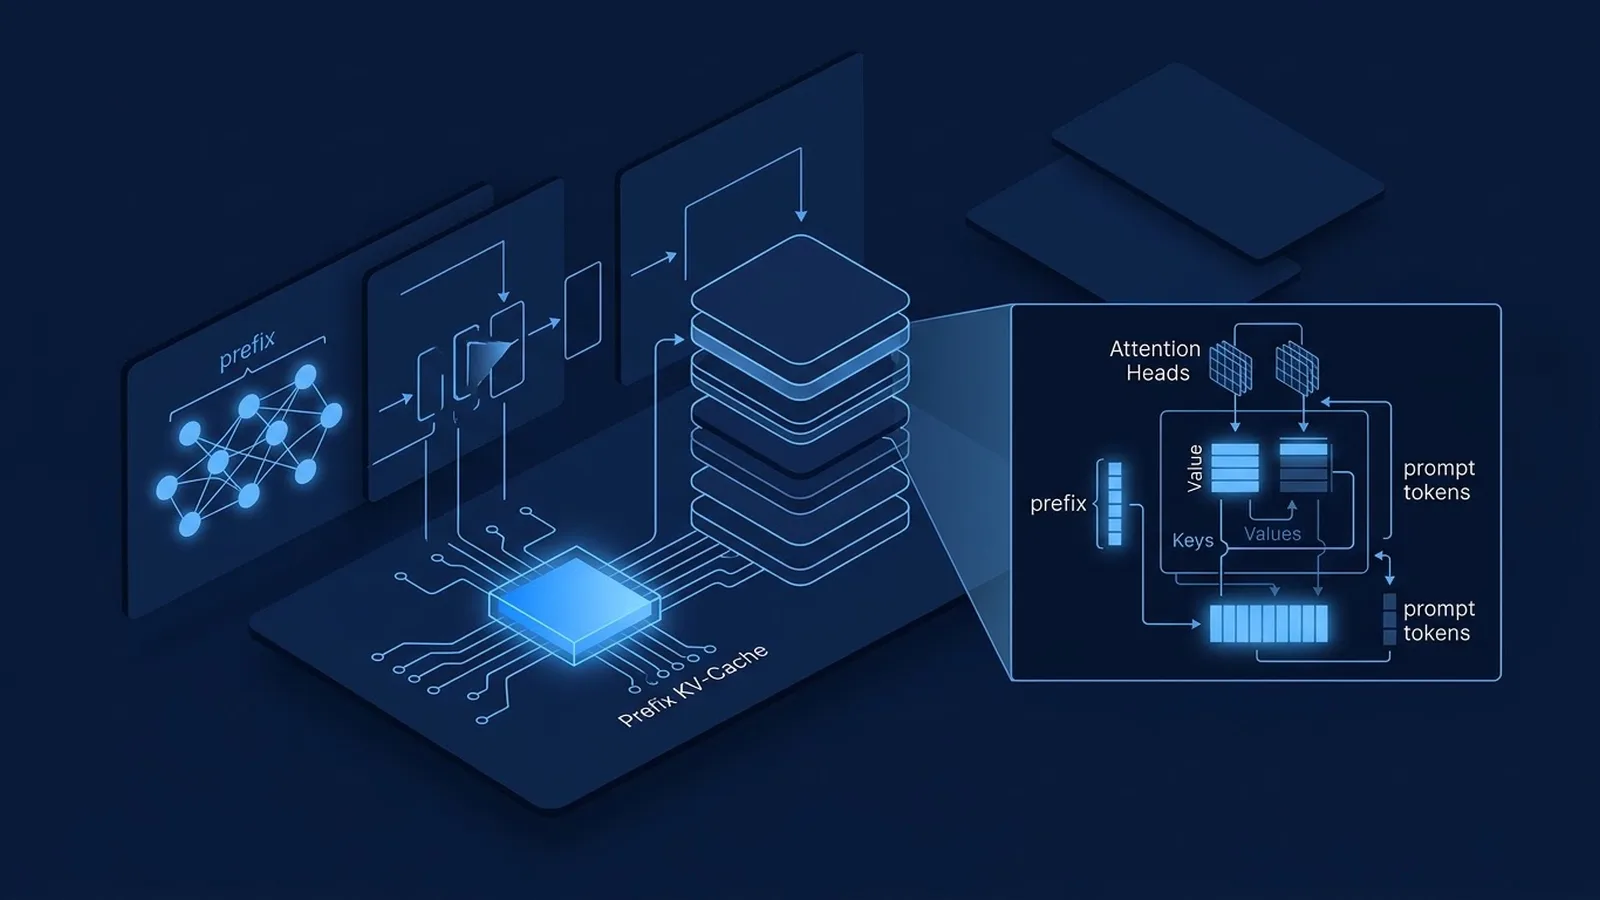
Prefix caching is an optimization mechanism within inference engines such as vLLM, TensorRT-LLM, and advanced cloud APIs. The principle relies on reusing the computed attention states for a fixed prefix of a prompt. When consecutive requests begin with the same sequence of tokens — such as a standardized system prompt, domain-specific rules, or background context — the inference engine doesn't need to re-run the prefill phase for those specific tokens. This saves considerable computing power on the GPU and reduces the latency before the first response token appears.
In a traditional setup, the model recalculates the interactions between all tokens in the attention layers for every incoming prompt. With prefix caching, the server recognizes that the first thousands of tokens exactly match an already cached block in GPU memory. The calculated Key and Value (KV) states are loaded directly, drastically reducing the time-to-first-token. To ensure such structures remain robust in practice and don't change unintentionally due to sloppy string concatenation, the article on reusable prompt components helps with correctly separating fixed and dynamic elements.
2. In-depth workings of the KV cache in transformers
To understand how prefix caching pays off, it's necessary to look at the internal workings of the Transformer architecture. During the initial processing of a prompt (the prefill phase), all input tokens are sent through the layers in parallel. This generates, for each layer and each attention head, representations that are stored in the KV cache, so the model doesn't have to recompute the context every time during the autoregressive generation of output tokens. The size of this cache scales directly with the length of the input.
Normally, this cache is cleared immediately after a request completes to free up memory for other users. With prefix caching, a specific part of the cache — namely that of the static system instructions — is retained and linked to a hash of the prefix. If a new request comes in with exactly the same hash at the start, the engine directly links the existing memory block to the new session. This not only saves computing power but also significantly increases the server's concurrent throughput.
3. Modular prompt structuring and the influence of hash validation
The way a cache works is entirely binary: a prefix is either identical or it isn't. A single changed space, an altered capital letter, or a dynamic timestamp at the beginning of the prompt completely changes the hash value of the prefix. This immediately leads to a cache miss, after which the server still has to calculate the entire input from scratch. Correctly structuring the input is therefore a fundamental requirement for stability.
This calls for a discipline in which the prompt is treated as real source code. Anyone who wants to dive deeper into this will find, in the guide on prompt version control practical tools for making changes in a controlled way. By strictly placing fixed instructions, JSON schemas, and basic examples at the front, and consistently moving dynamic user input or unique session parameters to the back, the prefix stays stable and a high cache hit ratio is guaranteed in all production scenarios.
4. Token costs, caching mechanisms, and the financial impact
The economic motivation behind prefix caching is at least as important as the technical gain in latency. In large-scale production applications, the costs of large context windows add up quickly. Many modern cloud providers and inference platforms reward the use of reusable prefixes by billing cached input tokens at a significantly lower rate — often up to eighty to ninety percent cheaper than uncached tokens, which fundamentally changes operational economics.
This fundamentally changes the economics of prompt design. Where developers were previously forced to keep system prompts as short as possible to save costs, prefix caching actually makes it attractive to add rich, detailed instructions and numerous factual frameworks. Because the fixed prefix is processed once and then retrieved from the cache at negligible cost, the benefits of in-depth guidance outweigh the operational downsides. For a detailed calculation of the financial aspects and savings per thousand tokens, the article on the financial impact of token costs and caching is a must-read.
5. API implementations and context caching in cloud infrastructure
Different inference engines and cloud providers have implemented their own methods for enabling prefix caching. Some open-source systems work fully automatically via block-level memory management, while commercial APIs require explicit parameters or headers to indicate which block should be retained. It's important to thoroughly study the specific documentation of the chosen platform.
| Platform or Engine | Caching Method | Threshold / Minimum Length | Typical Cost Effects |
|---|---|---|---|
| vLLM (Open Source) | Automatic Block-Level KV Caching | 16 tokens per memory block | Reduction in GPU memory usage and higher throughput |
| Anthropic Claude API | Explicit `cache_control` headers | Minimum 1,024 tokens per cache block | Up to 85% discount on cached input tokens |
| Google Gemini API | Cached Contents API | Minimum 32,768 tokens | Significant cost reduction for long-lived context |
Anyone wanting to know more about the broader infrastructure at API providers can consult the explanation on context caching in LLM APIs. When designing the application architecture, it's crucial to take the chosen provider's thresholds into account. Short instructions of two hundred tokens barely benefit from cloud-based caching, since they don't meet the minimum length requirement, whereas they yield immediate returns locally in vLLM.
6. Common mistakes and the causes of unexpected cache misses
In practice, it regularly happens that the cache hit ratio lags behind despite the same system prompt seemingly being used. This phenomenon is almost always caused by subtle variations in how the string is constructed before it reaches the inference engine. It's therefore essential to watch out for common sloppiness in the application logic that unintentionally changes the hash.
Typical culprits that immediately break the cache include putting a dynamic timestamp or unique request ID at the opening of the system prompt, varying orders of optional instruction blocks caused by sloppy string concatenation in the backend, inserting user-specific metadata directly at the top instead of the bottom, and inconsistent whitespace usage between microservices.
7. Measurement methods and monitoring cache efficiency
To verify whether prefix caching is actually paying off in a production environment, it's not enough to rely on theoretical expectations. Developers need to closely monitor the telemetry of the inference gateway. Important metrics here are the cache hit rate, the average prefill latency per request, and the effective drop in the number of billed input tokens over a longer period.
When monitoring shows that the hit rate fluctuates irregularly, this usually points to fragmentation of requests across different client applications or inconsistent templating. Centralizing prompt construction within an optimized gateway ensures that identical requests retain exactly the same prefix hash before reaching the inference layer, resulting in stable performance.
8. Limitations and edge cases under intensive use
Although prefix caching offers significant benefits, the technique also has clear limits and edge cases that need to be taken into account. For instance, caching KV states requires significant reservations of GPU memory (VRAM). Under extremely high concurrency with widely varying prefixes, memory fragmentation can occur, which can put pressure on the total capacity of the inference server if the cache eviction policies aren't properly tuned.
In addition, the technique is less effective in applications where every user receives a fully unique, personalized system prompt. If the overlap between different requests is negligible, maintaining the cache yields little benefit and its management only adds extra overhead to the engine. It's therefore important to apply prefix caching selectively, where the largest volumes and most stable instruction sets are found.
9. Future outlook in multi-agent systems
As AI architectures shift from simple question-and-answer chatbots to complex multi-agent systems and long-running autonomous workflows, the importance of efficient memory management grows exponentially. Agents generate thousands of intermediate steps, tool calls, and context switches in which the same basic instructions and tool definitions are repeatedly sent over the network.
By combining a stable base prefix with advanced caching strategies, operational costs and response times remain manageable, even under highly intensive autonomy and complex reasoning loops. Prefix caching has thus grown into an indispensable pillar of modern LLM engineering. Anyone who carefully structures prompts and consistently moves dynamic data to the back builds robust applications that respond faster and handle scarce hardware resources considerably more efficiently.
10. Conclusion and practical guidelines
Effectively deploying prefix caching requires a deliberate shift in how we as developers approach prompt design. Where the focus used to be on minimal length to work around costs and context limits, modularity and stability are now central. By placing fixed instructions at the front, isolating dynamic variables, and taking the monitoring of cache hits seriously, you transform a fragile prompt pipeline into a predictable, fast, and highly cost-efficient subsystem for any modern AI architecture.